Life sciences / TESSERA / PARALLAX
TESSERA: separating bacterial lineage from mobile genetic context
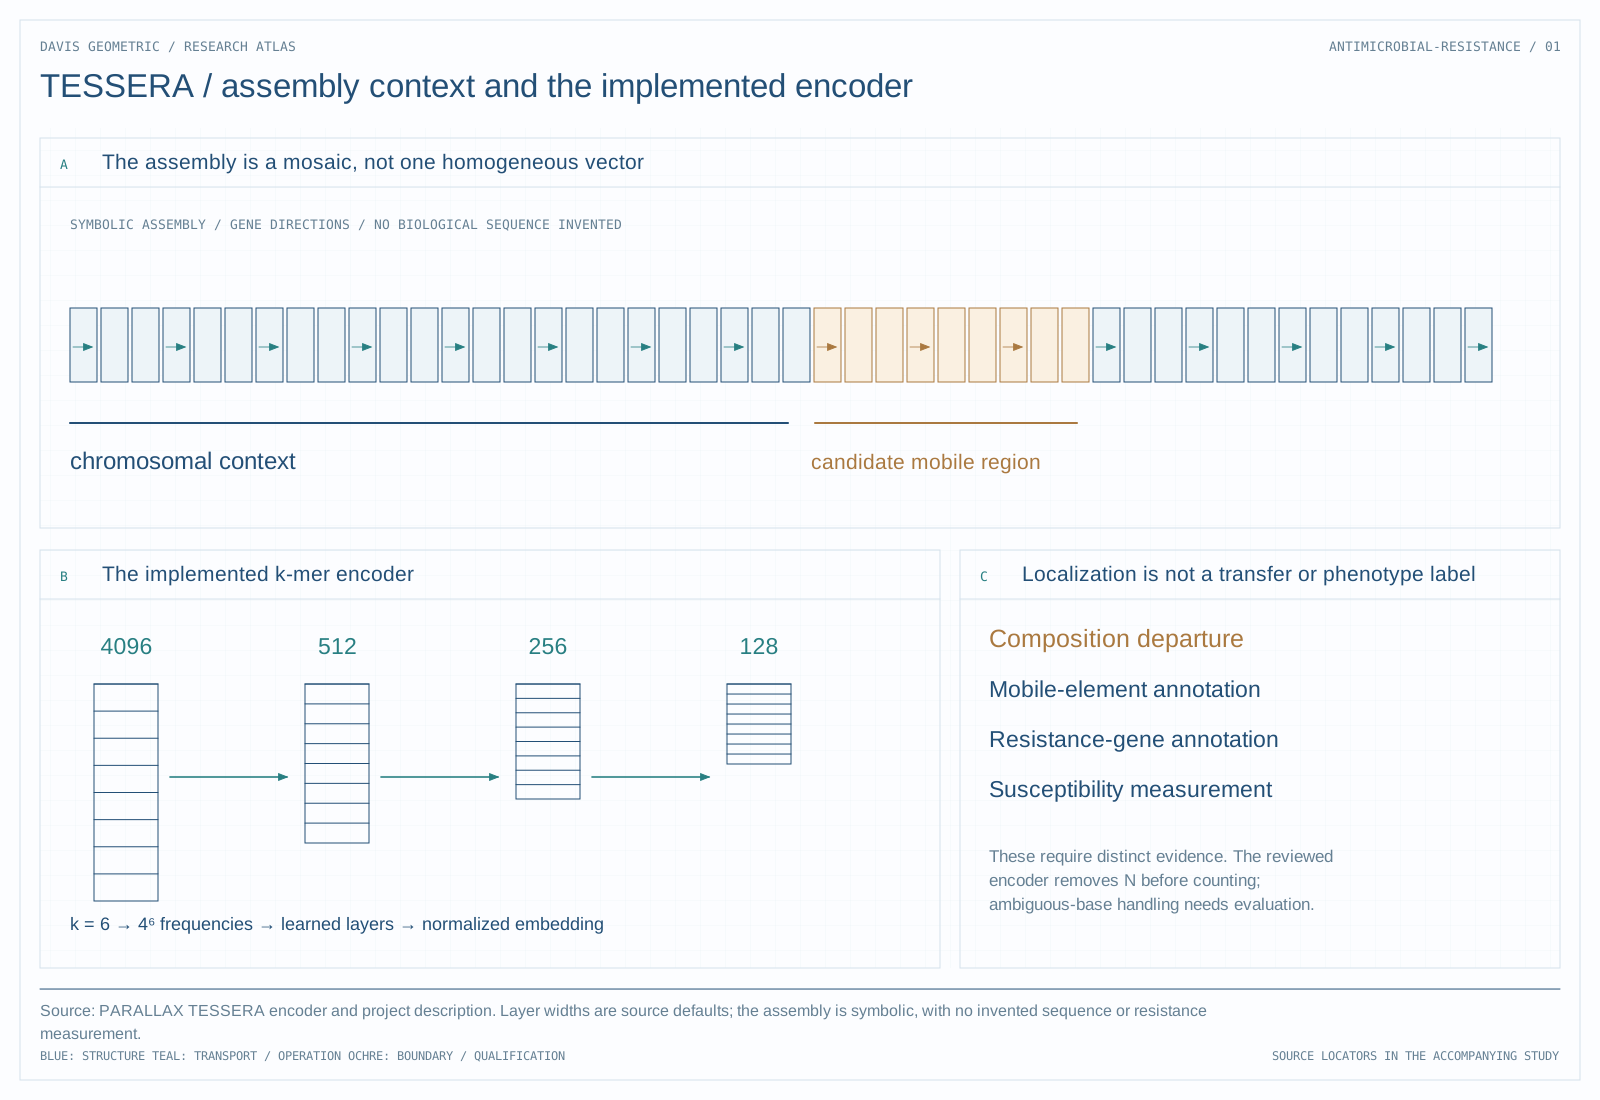
TESSERA represents bacterial assemblies as a mosaic: a relatively persistent chromosomal context and potentially mobile components. It investigates whether a compositional mismatch can help locate changes worth biological review.
Research settingIndependent
TL;DR
In brief
The question
Can a representation that separates a bacterial genome's persistent chromosomal context from its potentially mobile segments help locate changes worth biological review?
What the work does
The work builds TESSERA, a k-mer compositional encoder and pipeline for bacterial assemblies inside the PARALLAX platform, which accepts FASTA uploads and returns clustering, resistance-gene and transfer outputs.
What is still open
Whether a compositional departure marks a real transfer event, and whether any of it tracks measured resistance, is unestablished; both need independent evidence.
Available recordPlatform and representation descriptions; transfer events and resistance phenotypes require independent evidence.
From the research record
Inspect the work
Original figures, recorded values, and explicit model details. Each exhibit identifies its source and what the comparison means.
The implemented k-mer encoder, layer by layer
Scroll horizontally to inspect the full table →
| Step | Size / operation | Meaning |
|---|---|---|
| Count sequence words | k = 6; 4⁶ = 4,096 features | Frequency vector over A, C, G, T words |
| Normalize counts | Divide by the total counted words | Removes total-count scale |
| Hidden layer 1 | 4,096 → 512; ReLU; dropout 0.2 | Learned projection |
| Hidden layer 2 | 512 → 256; ReLU; dropout 0.2 | Learned nonlinear representation |
| Output | 256 → 128; L2 normalization | Unit-length embedding |
Default KmerEncoder configuration in the reviewed source. No trained weights or predictive accuracy are implied by these layer sizes. Its preprocessing removes N characters before counting, which can create artificial adjacency across ambiguous bases and needs evaluation.
tessera_encoder.py · KmerEncoder.__init__, count_kmers and forward
Three outputs that must not share one accuracy claim
Scroll horizontally to inspect the full table →
| Output in the project | Evidence type needed to evaluate it | Unit of comparison |
|---|---|---|
| Outbreak clustering | Independently supported outbreak / lineage labels | Assembly or isolate |
| Resistance-gene detection | Independent sequence annotation | Gene or region |
| Horizontal-transfer tracking | Supported mobile-element / transfer evidence | Segment and genomic context |
The task names come from PARALLAX; the evidence and comparison columns are the editorial evaluation map. No clinical resistance or transfer-rate measurements are present in this source.
README.md · TESSERA description and analysis gateway
The research in context
Antibiotic resistance does not only descend through a bacterial lineage. Resistance determinants also travel on mobile elements such as plasmids and integrons, moving between unrelated organisms, so two isolates may share a drug-resistant phenotype without sharing recent ancestry. Infection control needs both answers: whether two isolates belong to the same outbreak strain, and whether a resistance gene was inherited or acquired. Whole-genome sequencing supplies assemblies, but a single summary vector over an assembly mostly encodes which organism it is, while the acquired portion is a small fraction of the sequence. The clinically decisive outcome, whether the organism survives a given drug, remains a laboratory measurement rather than a sequence property.
TESSERA is one of three tools in PARALLAX, a genomic analysis service the project deploys on Modal's serverless GPU containers. Each tool has its own encoder and pipeline module: a k-mer encoder for bacterial assemblies here, ESM-2 protein embeddings for the viral tool, and mutation-profile encoding for the cancer tool. Shared utilities parse and validate FASTA, VCF and MAF uploads, and a report generator returns a PDF alongside the JSON result. Requests arrive either at a unified gateway endpoint that routes by tool name or at a per-tool endpoint. The README describes the deployment as processing data in ephemeral containers, holding nothing in memory after analysis and keeping sequence data out of logs.
The platform's privacy design and its analytical claims are separate things. Ephemeral containers, in-memory processing and results returned rather than stored are properties of how the service runs; none of them bears on whether a compositional signal localises a mobile element. The numeric settings in the README's configuration listing, including a shared 64-dimensional latent dimension, a bacterial outbreak threshold of 0.85 and a T4 GPU, are defaults in a source file. They are not values fitted or checked against an evaluation set, and reading them as operating characteristics would overstate what the repository contains.
Why one embedding for an entire assembly can lose the question
The project descriptions use k-mer composition and a reduced representation of sequence windows. The proposed bundle separates a chromosomal backbone from plasmids and integrons. A segment whose composition departs from its surrounding context can then be examined as a possible mobile element rather than averaged into a whole-genome vector.
The older site calls this departure “shear.” That name identifies a proposed representation statistic. Its magnitude does not by itself date a transfer event or establish the donor, recipient, or mechanism.
Three outputs with different truth conditions
PARALLAX lists outbreak clustering, resistance-gene detection, and horizontal-transfer tracking under the bacterial analysis tool. A cluster of related assemblies, an annotated resistance determinant, and a measured resistant phenotype are three different outputs.
Assembly quality, lineage composition, and contamination can affect a geometric anomaly. Independent sequence annotations can help evaluate localization, while susceptibility measurements are needed for phenotype claims. A single threshold cannot validate all three tasks.
The next research step
A representative study should preserve segment-level predictions and compare them against independently annotated mobile regions, then evaluate resistance separately. Lineage-aware splits are necessary to show that the representation learns more than organism identity.
Background mathematics and definitions
Represent windows or annotated elements while retaining their assembly coordinates and quality information. Compare composition, sequence homology, mobile-element context, and any measured phenotype as distinct evidence channels. Define the neighborhood metric before choosing a threshold.
- Assembly window
- A stated interval in a reconstructed sequence.
- Transfer candidate
- A hypothesis about sequence history, not a confirmed event.
- Resistance phenotype
- A measured response under a specified susceptibility protocol.
Illustrative example
Two unrelated windows can share a similar nucleotide composition while differing in sequence and function. A composition-based retrieval can place them close together; an independent annotation must determine whether the similarity supports the intended biological hypothesis.
This background example is separate from the source records and the main technical figure.
Source record
Additional source versions reviewed
-
parallax/README.mdLocal project manuscript or report · not republished here
No new experiments are reported in this research note. Figure captions distinguish saved research records, source-model calculations, and explanatory diagrams.