Algorithms & computing / MARCELLA / attention / cache
MARCELLA: separate the substrate, the gate, and the generator
MARCELLA is several related experiments rather than one model with one benchmark. The current companion distinguishes a reply-composition runtime over GIGI from a separate line of generative language-model research.
Research settingIndependent
TL;DR
In brief
The question
Can a language system built on an explicit geometric substrate, rather than learned weights alone, predict or compose text under matched baselines and know when to abstain?
What the work does
A next-token predictor built from corpus counts and fixed grammatical coordinates without gradient training, and a runtime composing cited replies from indexed GIGI bundles behind a distance-based refusal gate.
What is still open
Whether small held-out gains over Kneser–Ney smoothing persist on larger corpora, and how the refusal gate behaves beyond a 24-prompt rubric.
Available recordVersioned project descriptions and reported measurements; results from different runtimes are not pooled.
From the research record
Inspect the work
Original figures, recorded values, and explicit model details. Each exhibit identifies its source and what the comparison means.
Keep the experiments and outputs separate
Scroll horizontally to inspect the full table →
| Research component | Object under study | Finding / behavior recorded by the companion |
|---|---|---|
| Reply composition | Indexed source-backed response components | Voice opener, framing, citation and closing are assembled |
| Knowledge gate | Question relative to the indexed corpus | Refusal depends on source coverage |
| Multi-view, closed-form model | Separate representations of the input | Complementarity helped the tested models |
| Multi-view, transformer capacity | Same research question in a higher-capacity model | Reported gain washed out |
| Contrastive alignment | Aligning views versus keeping them separate | Reported loss relative to retaining perspectives |
Qualitative findings from distinct experiments; no missing benchmark values have been filled in. A retrieval runtime result is not a language-model perplexity or decoding-speed result.
The research in context
Most current language models are transformers: networks with millions to billions of learned weights that predict the next token by attending over the preceding context. Their knowledge is spread across those weights, which makes it hard to say where an answer came from, to correct one fact without retraining, or to make the model decline questions outside what it knows. Before neural models, n-gram methods predicted the next word from counts of short word sequences, adjusted by smoothing techniques such as Kneser–Ney so that unseen sequences are not ruled out. Those methods remain the natural baseline for any count-based predictor.
The pure-fiber paper (May 2026) places each vocabulary word on a bundle. The base coordinate lies on the seven-dimensional sphere, taken from a truncated SVD of the corpus word co-occurrence (PPMI) matrix; the fiber holds grammatical coordinates for person, animacy, tense (a circle), modality and part of speech, assigned from part-of-speech tagging and WordNet. Training is a database insert, reported at 121 seconds, with mixture weights set by derivative-free search on held-out data. MARCELLA’s runtime uses the same bundle structure on a 384-dimensional substrate: a question’s distance from the indexed records is compared with a calibrated border of 0.74–0.80 before any reply is composed.
The paper’s closest comparison sets the predictor against the strongest non-neural baseline on the same split. On Alice in Wonderland (8,254 training tokens, 75 test sentences), the fiber-kernel residual reaches perplexity 146.11 against 148.18 for Kneser–Ney with word classes; the paper treats this as an exploratory pilot because its interval crossed zero. On a 1,000-sentence WikiText-2 validation subsample it reports 341.56 against 345.98 for Kneser–Ney, a 1.28% reduction, while a control with shuffled fiber coordinates gains 0.26%. Most of the larger reduction from the classical bigram baseline comes from Kneser–Ney smoothing itself.
A response assembled from an indexed substrate
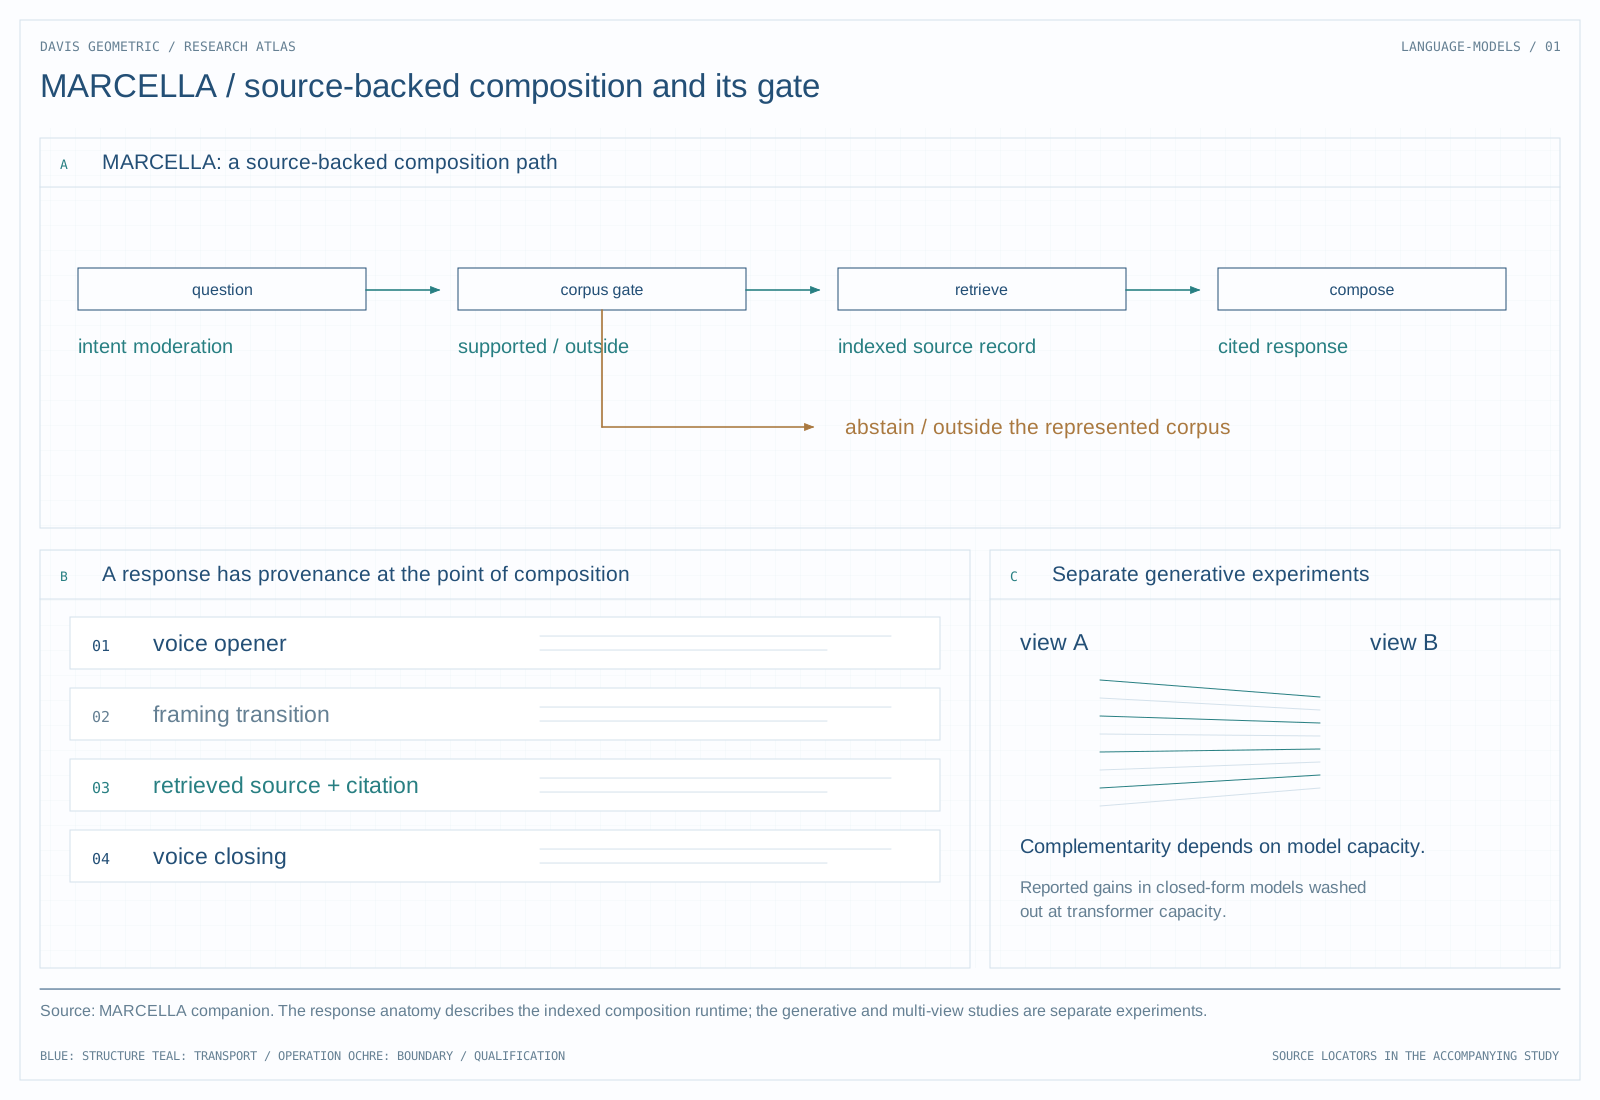
The companion describes replies composed from a voice opener, a framing transition, a cited source, and a closing. These components are retrieved from indexed bundles. An external language-model moderator gates intent at the entrance, while the described reply path assembles source-backed content rather than freely generating the answer.
The knowledge gate measures whether a question falls within the represented corpus. This is a concrete abstention mechanism: deciding when the system has a source to answer from. A distance threshold in one corpus should not be read as a universal boundary between knowledge and ignorance.
The generative experiments ask a different question
The same page records a from-scratch generative model, voice adaptation, and multi-view representations. It reports that multi-view complementarity helped the tested closed-form models but washed out at transformer capacity; it also reports that contrastive alignment lost to retaining separate perspectives. These negative findings explain why retrieval and generation should not share a single success headline.
Older catalog entries also cover speculative decoding, cache retention, attention spectra, and context. They change different parts of a language system. A perplexity result for one model cannot establish a decoding speedup or a cache-compression result for another.
The next research step
Choose the artifact being evaluated before choosing the metric: source fidelity and refusal behavior for the composition runtime, held-out likelihood for a generative model, or latency and acceptance rate for speculative decoding.
Background mathematics and definitions
Freeze a tokenizer and held-out sequence set. Define next-token loss on exactly those tokens. Treat geometric retrieval or cache selection as an intervention with an explicit resource budget and a fallback policy. Keep results from different Marcella versions in separate experiment records.
- tᵢ
- Token i under the frozen tokenizer.
- p
- The evaluated model’s conditional distribution.
- L
- Mean negative log likelihood; the logarithm base must be stated.
Illustrative example
A cache hit that saves computation but returns an answer for the wrong context is not a valid speedup. In a toy comparison of two otherwise identical requests, changing a negation is a useful stress case: lexical closeness alone does not guarantee interchangeable outputs.
This background example is separate from the source records and the main technical figure.
Source record
- Marcella project material.
- Pure-Fiber Language Modeling: Sequence Prediction by Geometric Query on a Real Fiber Bundle.
- Geometric Token Transport: Riemannian Parallel Transport as Sequential State Accumulation in Neural Sequence Processing.
- The Field Equations of Semantic Coherence: A Geometric Theory of Meaning, Curvature, and Reasoning in Transformer Architectures.
- The Davis Conjecture on Semantic Coherence: Context Windows as Holonomy Horizons in Functorial Transformers.
- The Geometry of Generative Reasoning: Gauge-Theoretic Transformers as Realizations of Semantic Sameness.
- Spectral Geometry of Transformer Cognition: Heat Kernel Analysis Reveals Functional Organization in Language Models.
- Davis Cache: O(1) Reasoning State Preservation via Topological Residue.
No new experiments are reported in this research note. Figure captions distinguish saved research records, source-model calculations, and explanatory diagrams.